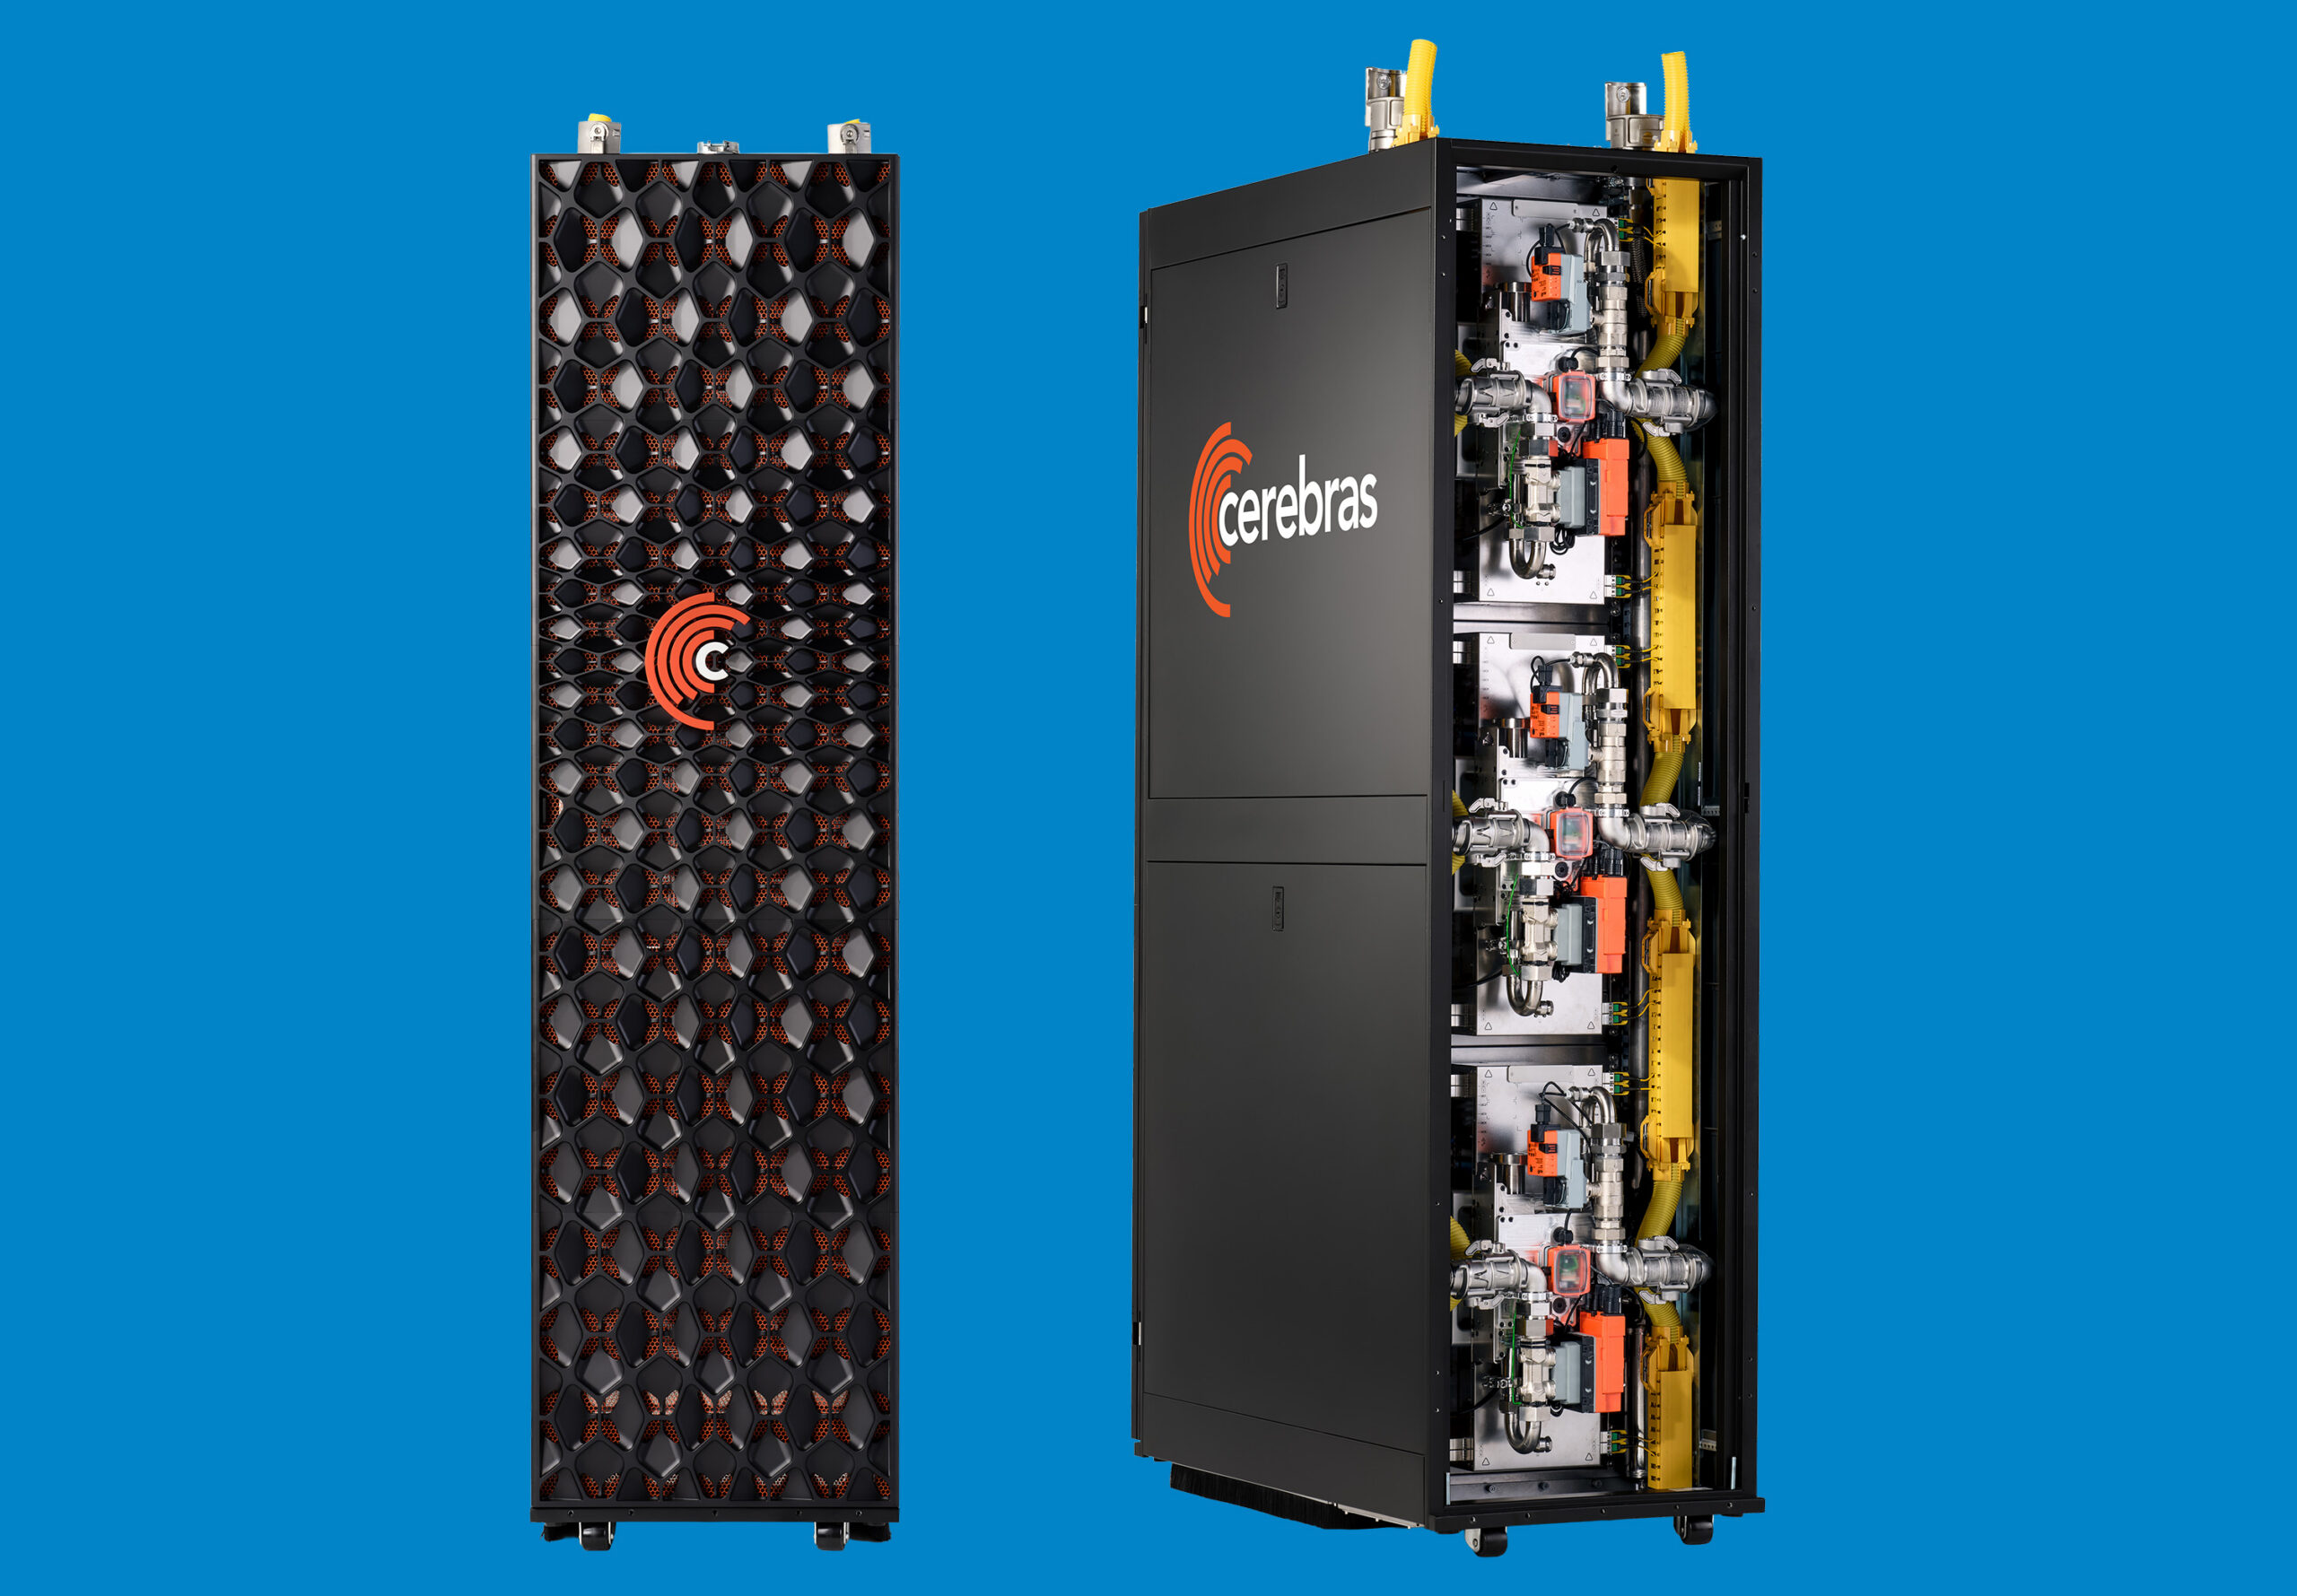
Cerebras Systems launched its CS-4 rack-scale server alongside a new wafer-scale chip, the WSE-3 Turbo, claiming up to 30 times more tokens per second per user than GPU-based systems on large language model inference. First shipments are expected this quarter.
The WSE-3 Turbo packs 4 trillion transistors and 900,000 AI-optimized cores onto a single wafer built on TSMC's 5nm process, doubling its predecessor's compute to 250 PFLOPS and its memory bandwidth to 43.2 petabytes per second, with 44GB of SRAM integrated directly on-chip. The CS-4 rack houses three of these wafers, delivering 750 PFLOPS of total AI compute and 129.6 petabytes per second of memory bandwidth — six times the throughput of a single CS-3 system and ten times higher throughput per watt.
The CS-4 is the first system built on Cerebras' new "Nexus" rack architecture, designed to let the company swap in future wafer generations, including planned CS-5 and CS-6 chips, without redesigning the rack. The launch intensifies competition in AI inference hardware, where Cerebras has positioned wafer-scale chips as a low-latency alternative to Nvidia GPU clusters for serving large models.